Remote Site Network Monitoring Over Satellite: Telemetry, Alerts, and Fault Isolation
Design remote site network monitoring over satellite with layered telemetry, local buffering, bandwidth budgets, alarm correlation, fault isolation, and acceptance tests.
What changed: Rebuilt the guide around service boundaries, layered evidence, edge collection, bandwidth and outage behavior, alarm correlation, troubleshooting, OT security, and testable operating runbooks; removed unsupported universal thresholds, bandwidth estimates, timer recommendations, and vendor-tool endorsements.
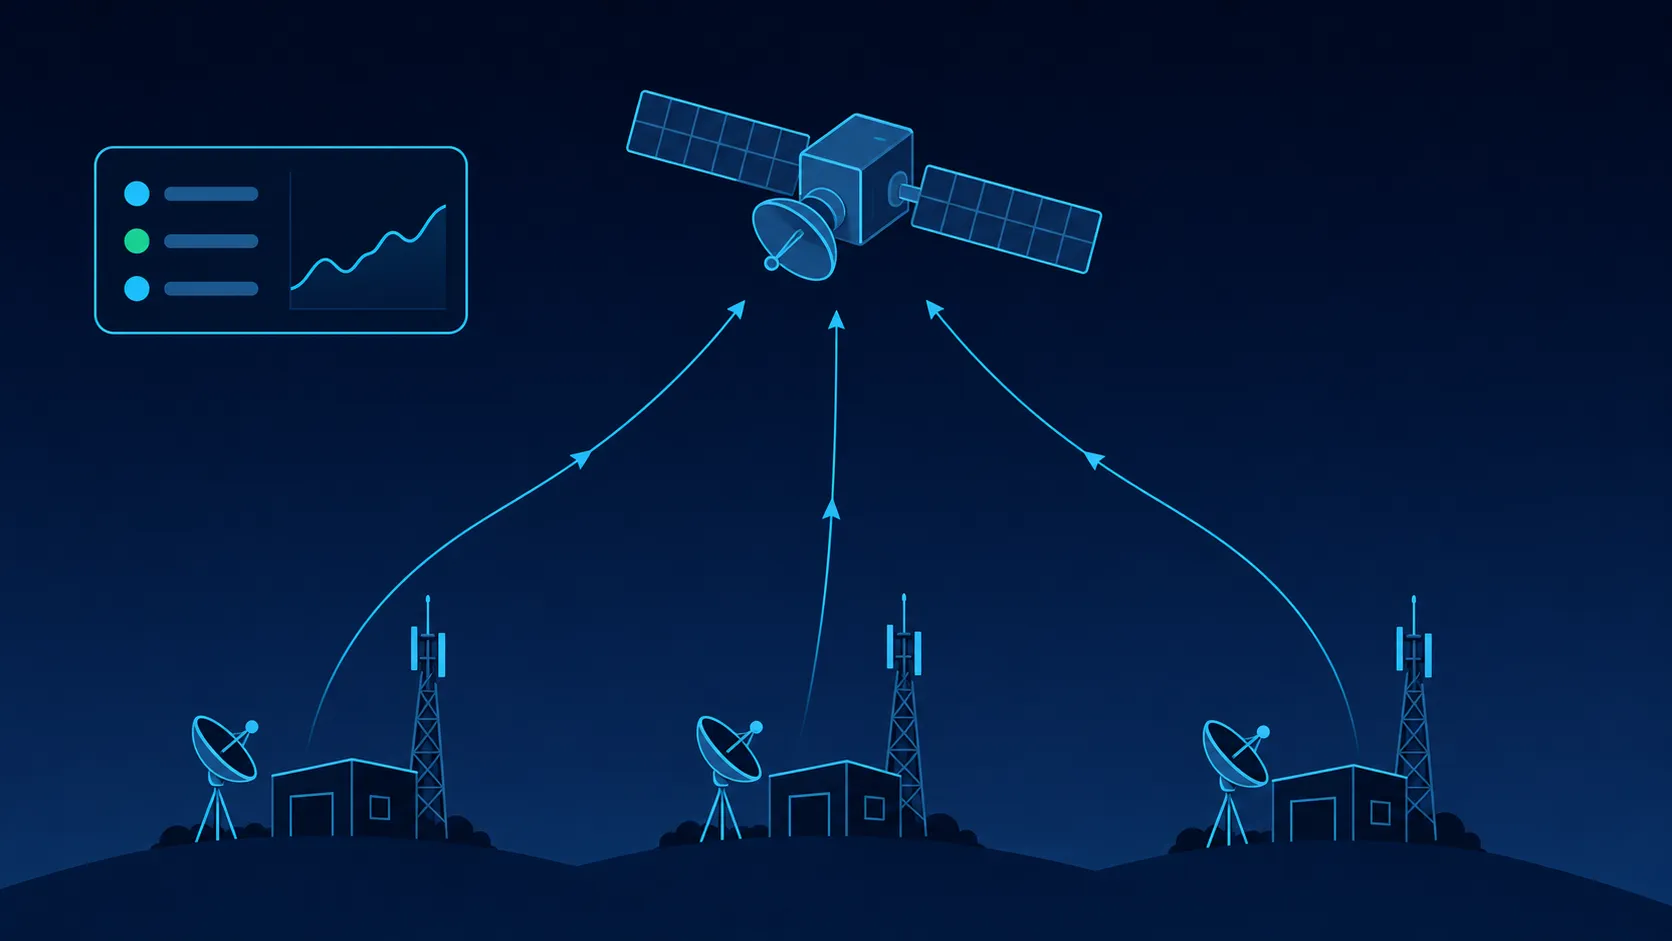
Remote site network monitoring over satellite must preserve useful evidence when the WAN is slow, impaired, or completely unavailable. The design should distinguish site power, terminal and RF health, IP forwarding, security services, and application outcomes; collect the right data at the right location; control telemetry volume; correlate dependent alarms; and retain enough local history to explain what happened after connectivity returns.
This page focuses on remote assets connected through satellite. For the central platform and operating functions, use Satellite Network Management System. For application timing and industrial telemetry, use SCADA Using Satellite Communication. For service-provider responsibilities, use Managed Satellite Services.
Scope note: Monitoring thresholds, polling intervals, retention, and response times must come from the equipment, service, application, safety, security, and contract requirements for the actual site. The examples here are design fields, not universal target values.
Quick Architecture Rule
useful remote monitoring = defined service outcomes
                         + layered local evidence
                         + controlled telemetry budget
                         + store-and-forward during outages
                         + dependency-aware alarms
                         + tested response runbooks
Monitoring is not successful merely because a central dashboard is green. A modem can remain locked while the IP path is impaired. The WAN can be healthy while DNS, VPN, identity, or the application is unavailable. When the satellite link fails, central silence cannot tell the NOC whether the entire site lost power or only the communications path.
Define What the NOC Must Know
Start from operational decisions rather than from every available metric. For each monitored outcome, record:
- service owner and affected users or process;
- normal, impaired, failed, recovering, and maintenance states;
- evidence source and measurement point;
- collection interval and acceptable data age;
- local retention needed during a WAN outage;
- alarm owner, severity, response, and escalation;
- safe remote action and actions that require local presence;
- evidence required to close the incident.
Use a coverage matrix:
| Outcome | Local evidence | Central evidence | Outage behavior | Alarm owner | Restoration test |
|---|---|---|---|---|---|
| Site power and environment | |||||
| Terminal and RF path | |||||
| IP forwarding and routing | |||||
| VPN, DNS, identity, and time | |||||
| Application transaction | |||||
| OT telemetry or approved command path |
This exposes monitoring gaps before they become troubleshooting gaps.
Collect Evidence by Layer
RFC 9232 frames network telemetry across management, control, forwarding, and external data sources. For a satellite-connected site, use a layered evidence model.
Site and Power Layer
Monitor the dependencies that can remove every higher layer at once:
- utility, generator, solar, battery, UPS, distribution, and transfer state;
- rack power, device input, temperature, humidity, enclosure, and cooling;
- antenna or radome environment where sensors are available;
- local controller health and edge collector storage.
If all devices disappear simultaneously, this layer helps distinguish site loss from communications loss. The NOC should know whether site telemetry has stopped because the collector lost power, the WAN failed, or the central platform stopped ingesting.
Terminal and RF Layer
Collect the measurements the terminal and provider actually expose, such as:
- receive lock, transmit authorization, registration, and operational state;
- receive quality, transmit level, waveform or adaptive-mode state;
- antenna pointing, blockage, tracking, or stabilization alarms where applicable;
- modem restarts, software, configuration, license, and certificate state;
- beam, gateway, network, and planned-maintenance events from the provider.
ITU-R S.2278-0 describes VSAT control and monitoring functions, including supervision by the network control and monitoring centre and terminal behavior when specified fault or control conditions occur. Map vendor-specific fields to stable operational meanings instead of assuming two modems use identical names or scales.
IP and Forwarding Layer
Measure the path from a deliberate source to a deliberate destination:
- interface and queue counters;
- route, next-hop, tunnel, and security-association state;
- delay, loss, variation, throughput, and retransmission evidence where useful;
- reachability to the provider handoff, enterprise edge, DNS, identity, and application destination;
- IPFIX or other flow records when traffic attribution is needed.
RFC 7011 defines the IPFIX architecture of metering, exporting, and collecting processes. Flow records can help explain capacity use, but export volume, templates, sampling, retention, and privacy must be engineered for the site.
Application and Operations Layer
Use safe synthetic checks that represent the protected outcome:
- DNS resolution through the intended resolver;
- VPN establishment and protected-path reachability;
- identity or certificate validation where appropriate;
- a read-only or otherwise safe application transaction;
- SCADA freshness, queue depth, or acknowledgment behavior without disturbing control;
- alarm-to-ticket, notification, acknowledgment, dispatch, and restoration timestamps.
Do not infer application availability from carrier lock or ping alone.
Choose the Collection Architecture
Central Polling
The central NMS queries devices across the satellite link. This simplifies platform administration, but every request and response consumes WAN capacity and depends on the path being available. High round-trip delay, congestion, handover, or intermittent loss can cause overlapping polls and false timeouts when terrestrial defaults are copied unchanged.
Use central polling when the monitored set is small, data volume is bounded, timeout behavior is tested, and loss of visibility during WAN failure is acceptable.
Local Edge Collection
A collector at the site polls local devices, receives events, evaluates local rules, buffers data, and forwards selected telemetry. This can reduce repeated WAN exchanges and preserve history during an outage. It also adds an asset that needs power, storage, software, configuration, security, monitoring, and recovery.
Use edge collection when device count, polling exchanges, log volume, outage evidence, or local decisions justify the operational overhead.
Hybrid Collection
Many sites benefit from a hybrid design:
- local collection for LAN, server, sensor, log, and high-volume device data;
- central or provider collection for gateway-side and network-wide satellite evidence;
- direct low-volume alarms for critical terminal or site states;
- scheduled or opportunistic upload of detailed history;
- independent application checks from more than one observation point.
Document which copy is authoritative when local and central observations disagree.
Create a Telemetry Budget
Monitoring competes with operational traffic. Estimate it before deployment:
telemetry load = polling requests and replies
               + events and logs
               + flow or packet records
               + synthetic probes
               + acknowledgements and protocol overhead
               + backlog upload after outages
For each data stream, record:
| Stream | Normal rate | Burst condition | Local retention | WAN priority | Drop/aggregation rule |
|---|---|---|---|---|---|
| Critical state changes | |||||
| RF and terminal metrics | |||||
| Device health | |||||
| Syslog or event messages | |||||
| Flow records | |||||
| Synthetic checks | |||||
| Outage backlog |
Test both steady state and bursts. A reboot, routing change, power recovery, scan, or software fault can create far more telemetry than the daily average. An outage backlog that uploads at line rate can cause a second brownout immediately after service returns.
Reduce Traffic Without Losing Evidence
- collect at the edge and send summaries when raw samples are not required centrally;
- use event-driven or on-change reporting where supported, with a periodic heartbeat to prove the collector is alive;
- choose metric-specific intervals from decision latency and trend needs;
- avoid broad discovery or full object walks during busy periods;
- filter repetitive logs close to the source while retaining security- and incident-relevant events;
- aggregate flow records or sample only when the resulting evidence still answers the operational question;
- compress batches when supported and schedule backlog upload under a controlled rate;
- prioritize alarms, health heartbeats, routing, DNS, identity, and time ahead of bulk history.
Every optimization needs a loss statement: what detail is discarded, what diagnosis becomes impossible, and who accepts that trade-off.
Design Store-and-Forward Behavior
When the satellite path is unavailable, the edge collector should follow a defined policy:
- continue collecting the metrics needed to reconstruct the incident;
- timestamp against a maintained local clock and record loss of time synchronization;
- preserve high-value events before routine samples;
- apply bounded storage and explicit eviction rules;
- protect buffered data against unauthorized access and corruption;
- mark gaps, resets, counter wraps, and collector restarts;
- reconnect with backoff rather than an uncontrolled retry storm;
- upload backlog under rate and priority control;
- prevent duplicate events from creating duplicate incidents.
Size retention from the longest credible outage plus access delay, collection rate, compression, safety margin, and data criticality. Test storage exhaustion rather than assuming it cannot occur.
Build Dependency-Aware Alarms
An unreachable site can produce hundreds of downstream symptoms. A useful alarm system identifies the likely parent event and preserves child evidence without paging on every consequence.
RFC 8632 provides a structured model for alarm inventory, state, notifications, shelving, and operator actions. Apply those concepts to a site dependency graph:
site power
  -> edge collector
  -> terminal / modem
  -> WAN path
  -> local router and security edge
  -> downstream devices and applications
Define:
- alarm identity, resource, severity, and probable cause;
- state change, acknowledgment, owner, and clear condition;
- parent/child dependency and suppression behavior;
- maintenance and shelving authority;
- flapping, hysteresis, and hold-down logic;
- ticket creation and update rules;
- retained child evidence for later root-cause analysis.
Suppression should reduce noise, not erase facts. If a modem loses lock, downstream device reachability alarms may be hidden from paging but retained as correlated evidence.
Treat Logs as an Engineered Data Source
RFC 5424 defines syslog originators, relays, collectors, facilities, and severities. For remote sites:
- normalize timestamps, time zones, host identity, severity, and device context;
- send through an authenticated and protected path appropriate to the environment;
- filter repeated low-value messages without dropping incident or security evidence;
- prevent a chatty device from consuming the WAN queue;
- retain locally when the collector is unreachable;
- test restart, duplicate, reordering, and backlog behavior.
Device severity labels are not automatically business severity. A device “critical” event can be redundant and non-service-affecting, while a quiet application freshness failure can be operationally critical.
Separate Fault Domains in the Runbook
Use a layered diagnosis sequence.
1. Confirm the Observation
- Is the user report current, repeatable, and tied to a specific application?
- Which observation points agree or disagree?
- Is monitoring data fresh, delayed, or replaying a backlog?
2. Check Site and Collector Health
- Is site power stable?
- Is the collector running, storing data, and synchronized well enough for event ordering?
- Did multiple devices restart together?
3. Check Terminal and RF Evidence
- Is the terminal registered, receive-locked, and authorized to transmit?
- Did receive quality, transmit behavior, pointing, waveform, or gateway state change from the site baseline?
- Is the event local, beam-wide, gateway-wide, or service-wide?
4. Check IP and Security Services
- Does the intended route exist and forward through the expected path?
- Are queues congested or dropping the protected class?
- Are VPN, DNS, identity, address, NAT, and certificate dependencies healthy?
5. Check the Application
- Does a safe transaction complete?
- Is data fresh, queued locally, duplicated, or out of order?
- Did the application reconnect after route or address change?
6. Escalate with a Dossier
Provide synchronized timestamps, site and service identifiers, application impact, terminal state, RF trend, path tests, recent changes, local power/environment state, and actions already taken. State what evidence is missing and which organization owns the next decision.
Establish Site-Specific Baselines
Static universal thresholds are unreliable. Build baselines after commissioning and through representative conditions:
- normal receive quality and transmit behavior by weather or operating state;
- delay, variation, loss, queue, and throughput by traffic class;
- expected registration, handover, or route-transition behavior;
- power and environmental ranges;
- daily and weekly utilization patterns;
- restart, outage, and recovery signatures;
- typical log and alarm volume.
Set warnings from equipment limits, link design, application requirements, provider evidence, and observed variance. Review thresholds after service, software, antenna, route, capacity, or application changes.
Secure the Management Plane
Monitoring systems hold topology, credentials, configurations, and privileged access. Protect them as operational infrastructure:
- use unique identities, least privilege, and separate read from change permissions;
- prefer authenticated and encrypted management protocols supported by the equipment;
- isolate management paths and control which sources can reach device interfaces;
- govern provider, vendor, and emergency remote access;
- protect configuration backups, buffered telemetry, logs, and API tokens;
- record administrative actions and configuration changes;
- maintain software, certificates, credentials, and trusted time;
- design a recovery path that does not require opening an uncontrolled bypass.
For OT sites, NIST SP 800-82 Rev. 3 emphasizes security controls that account for performance, reliability, and safety. Monitoring should not overload controllers, interfere with deterministic processes, or turn an enterprise compromise into direct control access.
Acceptance Tests
Data and Timing
- verify each required device and service appears with the correct identity;
- compare local values, central values, units, timestamps, and data age;
- prove counter, reset, clock-loss, and missing-data behavior.
WAN Conditions
- introduce controlled delay, variation, loss, congestion, and disconnection;
- confirm polls do not overlap uncontrollably or create false device failures;
- verify priority traffic survives telemetry bursts.
Outage and Recovery
- disconnect the WAN while local equipment continues operating;
- verify local collection, bounded storage, eviction, reconnect, and rate-controlled backlog upload;
- confirm the dashboard distinguishes live data from delayed history.
Alarm and Workflow
- trigger site-power, terminal/RF, IP-path, security-service, and application events separately;
- verify correlation, suppression, ticket, notification, escalation, and clear behavior;
- test planned maintenance and unstable recovery.
Security and Change
- verify authorized roles, denied paths, administrative logging, backup and rollback;
- confirm monitoring survives credential, certificate, software, or configuration renewal;
- retain test evidence, exceptions, corrective actions, owners, and retest results.
FAQ
What is the best monitoring architecture for a satellite-connected remote site?
It depends on device count, telemetry volume, outage duration, decision latency, security, and support capability. A hybrid model—local collection plus central and provider evidence—is often practical, but it must be justified and tested for the actual site.
What polling interval should be used?
There is no universal interval. Set it per metric from required detection time, device capacity, satellite path behavior, telemetry budget, and the cost of stale data. Test timeouts and concurrent polls under impairment.
How much bandwidth does monitoring consume?
Calculate it from the configured requests, responses, events, flow records, probes, overhead, retransmissions, and outage backlog. Generic per-site estimates are unreliable because device count and logging behavior vary widely.
How can the NOC tell RF failure from IP failure?
Compare layered evidence: site power, terminal registration and RF state, provider-side observations, routed probes, tunnel and DNS state, and a safe application transaction. No single metric proves every layer.
What happens to monitoring during a satellite outage?
The design should state what continues locally, how long it is retained, what is discarded first, how data is timestamped, and how backlog is uploaded without congesting the recovered link.
Should the provider and customer share one NMS?
They can use separate systems if the service defines measurement points, data exchange, timestamps, alarm ownership, and dispute handling. A shared dashboard does not replace a documented service boundary.
Related Guides
- Satellite Network Management System — NMS/NOC architecture, management functions, alarms, QoS, security, and operations
- Managed Satellite Services — service scope, responsibility, evidence, incident, and lifecycle requirements
- High Availability Satellite Networks — failure domains, detection, degraded traffic, and recovery tests
- Satellite Network Brownout — degraded-but-connected conditions and detection
- SCADA Using Satellite Communication — industrial traffic, timing, outage behavior, and acceptance
- Satellite Terminal Architecture — antenna, RF, modem, and IP terminal layers
- Ground Segment Architecture — gateway, hub, control, and terrestrial handoff functions
Author
Organizational byline for SATCOM Index technical content. A named technical reviewer appears separately only when identity, scope, and permission are verified.
Categories
More Posts
How to Calculate Satellite EIRP (Formula + Examples)
Calculate satellite EIRP from transmit power, antenna gain, and losses. Includes reproducible VSAT and beam-contour examples, EIRP density, ERP, and G/T.
Carrier-in-Carrier Satellite Links: How CnC Actually Works
Calculate Carrier-in-Carrier satellite bandwidth savings, then verify modem compatibility, transparent-payload loopback, power ratios, commissioning, and ROI.
Hybrid Satellite Networks: Multi-Orbit (LEO + GEO) Architecture and Design Considerations
Engineering guide to hybrid satellite network architecture—combining LEO and GEO orbits for latency, redundancy, and throughput optimization in enterprise and carrier deployments.